Research
UniBrain+: Multimodal Reasoning Enriches 3D Brain MRI Analysis with Incomplete Contrasts
- Accepted by MICCAI, 2026. Extension submitted to IJCV;
- Project Page (MICCAI version): https://medicalumm.github.io/unibrain.github.io/
- Codes are available at https://github.com/zhiyuns/UniBrain.
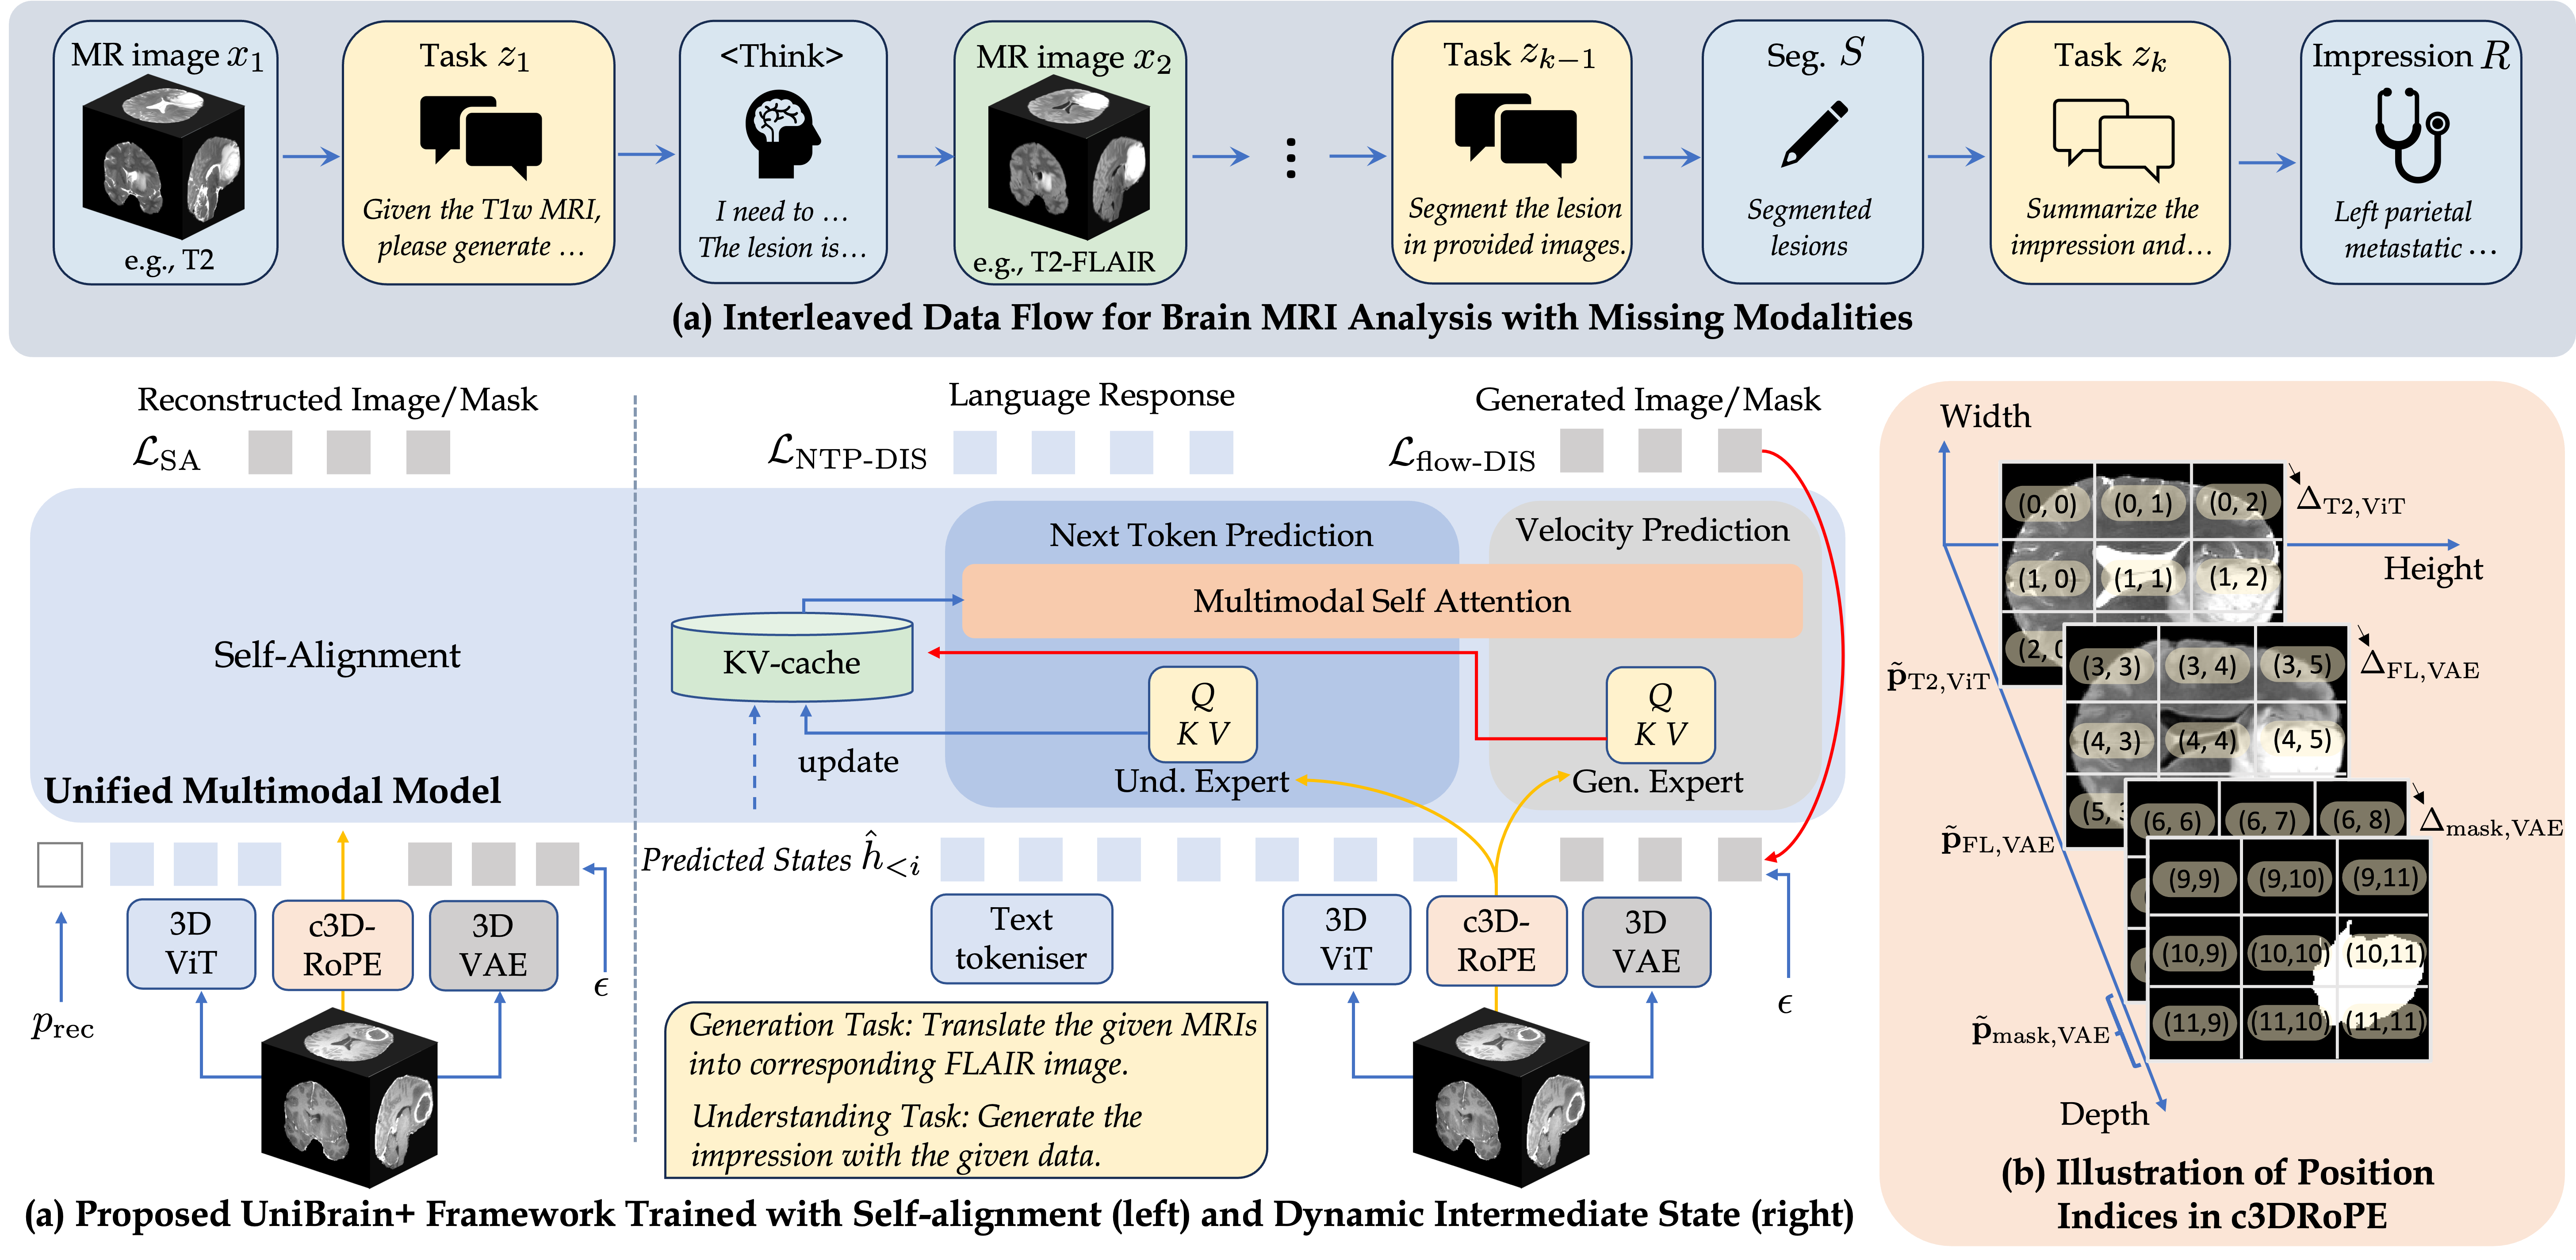
Multimodal large language models (MLLMs) inherit knowledge from LLMs and enable the integration and analysis of multimodal medical data. However, their applications to brain magnetic resonance imaging (MRI) face practical challenges, including heterogeneous imaging contrasts, the encoding of 3D anatomical features, and the lack of dense text captions for alignment with 3D images. In this paper, we introduce UniBrain+, a unified multimodal model that jointly performs imputation and analysis for multi-contrast brain MRI. Built on interleaved brain image-text data, UniBrain+ is able to perform brain MRI analysis with incomplete contrasts by including the synthesised images and descriptions as multimodal reasoning context. The model is equipped with 3D visual encoders and contrast-aware 3D rotary position embedding to capture 3D geometric information. A self-alignment objective alleviates the need for dense text captions for vision-language alignment by aligning dense visual features with their corresponding generative latents for image generation. Dynamic intermediate states further enable robust multimodal inference by exposing the model to generated visual context during training. Across multi-disease brain MRI datasets and various missing contrast settings, UniBrain+ achieves competitive performance in multi-contrast brain image understanding, with high-quality generated multimodal context.
Generalizable Low-dose CT Denoising with Noise-aware Visual Autoregressive Guidance
- Submitted to MedIA;
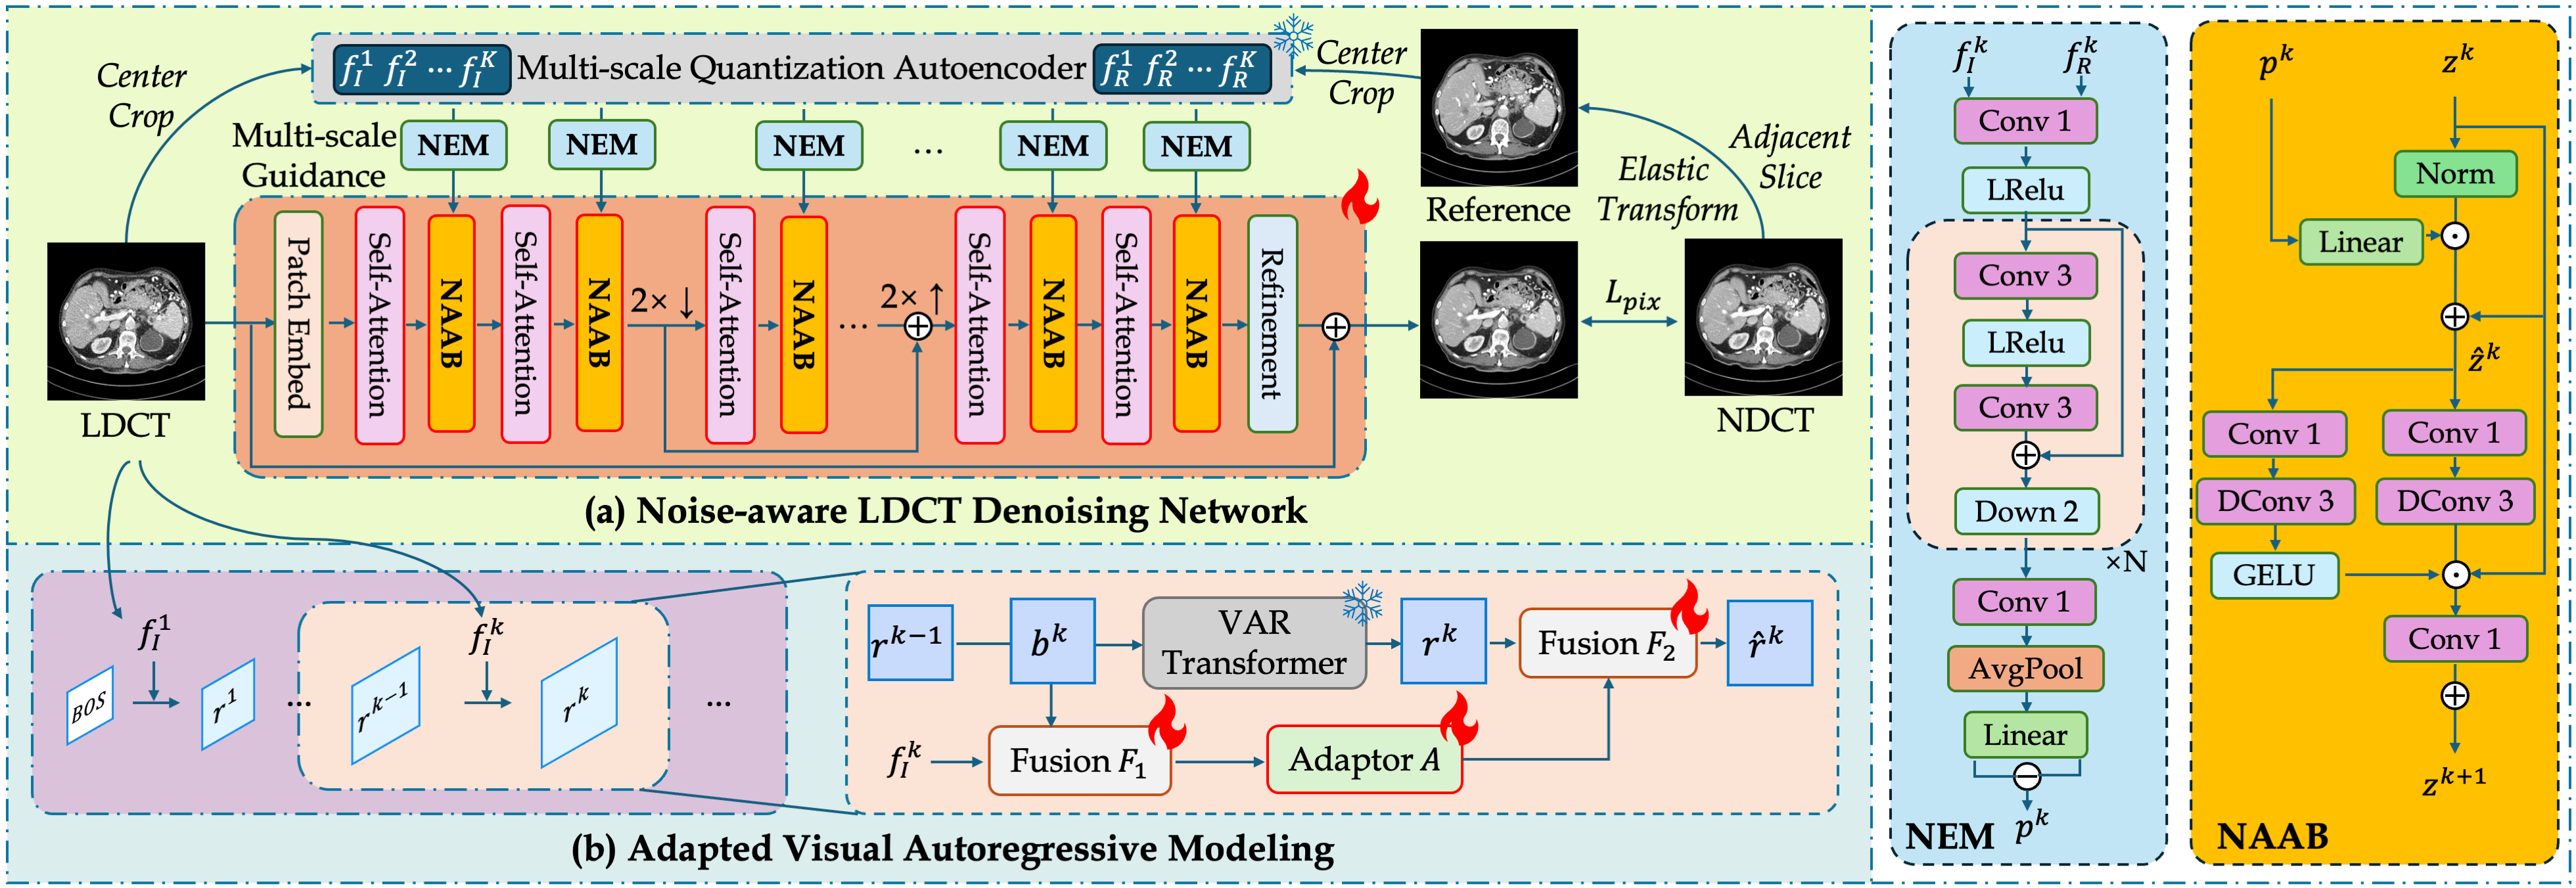
Low-dose computed tomography (LDCT) aims to reduce patient radiation exposure, yet the resulting noise can degrade image quality and hinder diagnostic accuracy, making it a critical focus in medical use. Due to the challenges of acquiring large-scale paired LDCT and normal-dose CT (NDCT) scans in clinical practice, existing deep learning models are predominantly trained on specific simulated datasets, limiting their ability to generalize effectively to real-world LDCT data. Although mixed-dose training strategies have been proposed, they often struggle to maintain consistent image quality across various dose levels and noise patterns. To address these limitations, we propose a Multi-scale Autoregressive prior-guided Noise-aware DEnoising framework (MANDE). We first incorporate multi-scale noise features encoded by VQVAE, enabling the denoising model to learn noise patterns during training. To impose effective guidance during inference, we further employ an adapted visual autoregressive model (VAR) to progressively capture complex noise distributions and generate alternative latent-space noise patterns. This design enables MANDE to efficiently adapt to diverse noise subtypes while overcoming the domain gap and misalignment issues encountered with pretrained VAR models in LDCT denoising tasks. Experimental results on both simulated and real-world datasets demonstrate that MANDE outperforms previous state-of-the-art denoising methods, offering marked improvements in generalization to unseen clinical scenarios. Specifically, the proposed method outperforms the baseline Restormer method by up to +1.3 (PSNR) in generation fidelity and +1.6\% (DSC) in downstream tasks with negligible additional inference time. MANDE also demonstrates its plug-and-play effectiveness across various denoising methods. Our codes will be publicly available.
Enhancing Generative Models for Modality Imputation of 3D MRIs via Consistency-aware Refinement and Super-resolution Guidance
- Accepted to TNNLS, 2026;
- Codes are available at https://github.com/zhiyuns/CRSG.
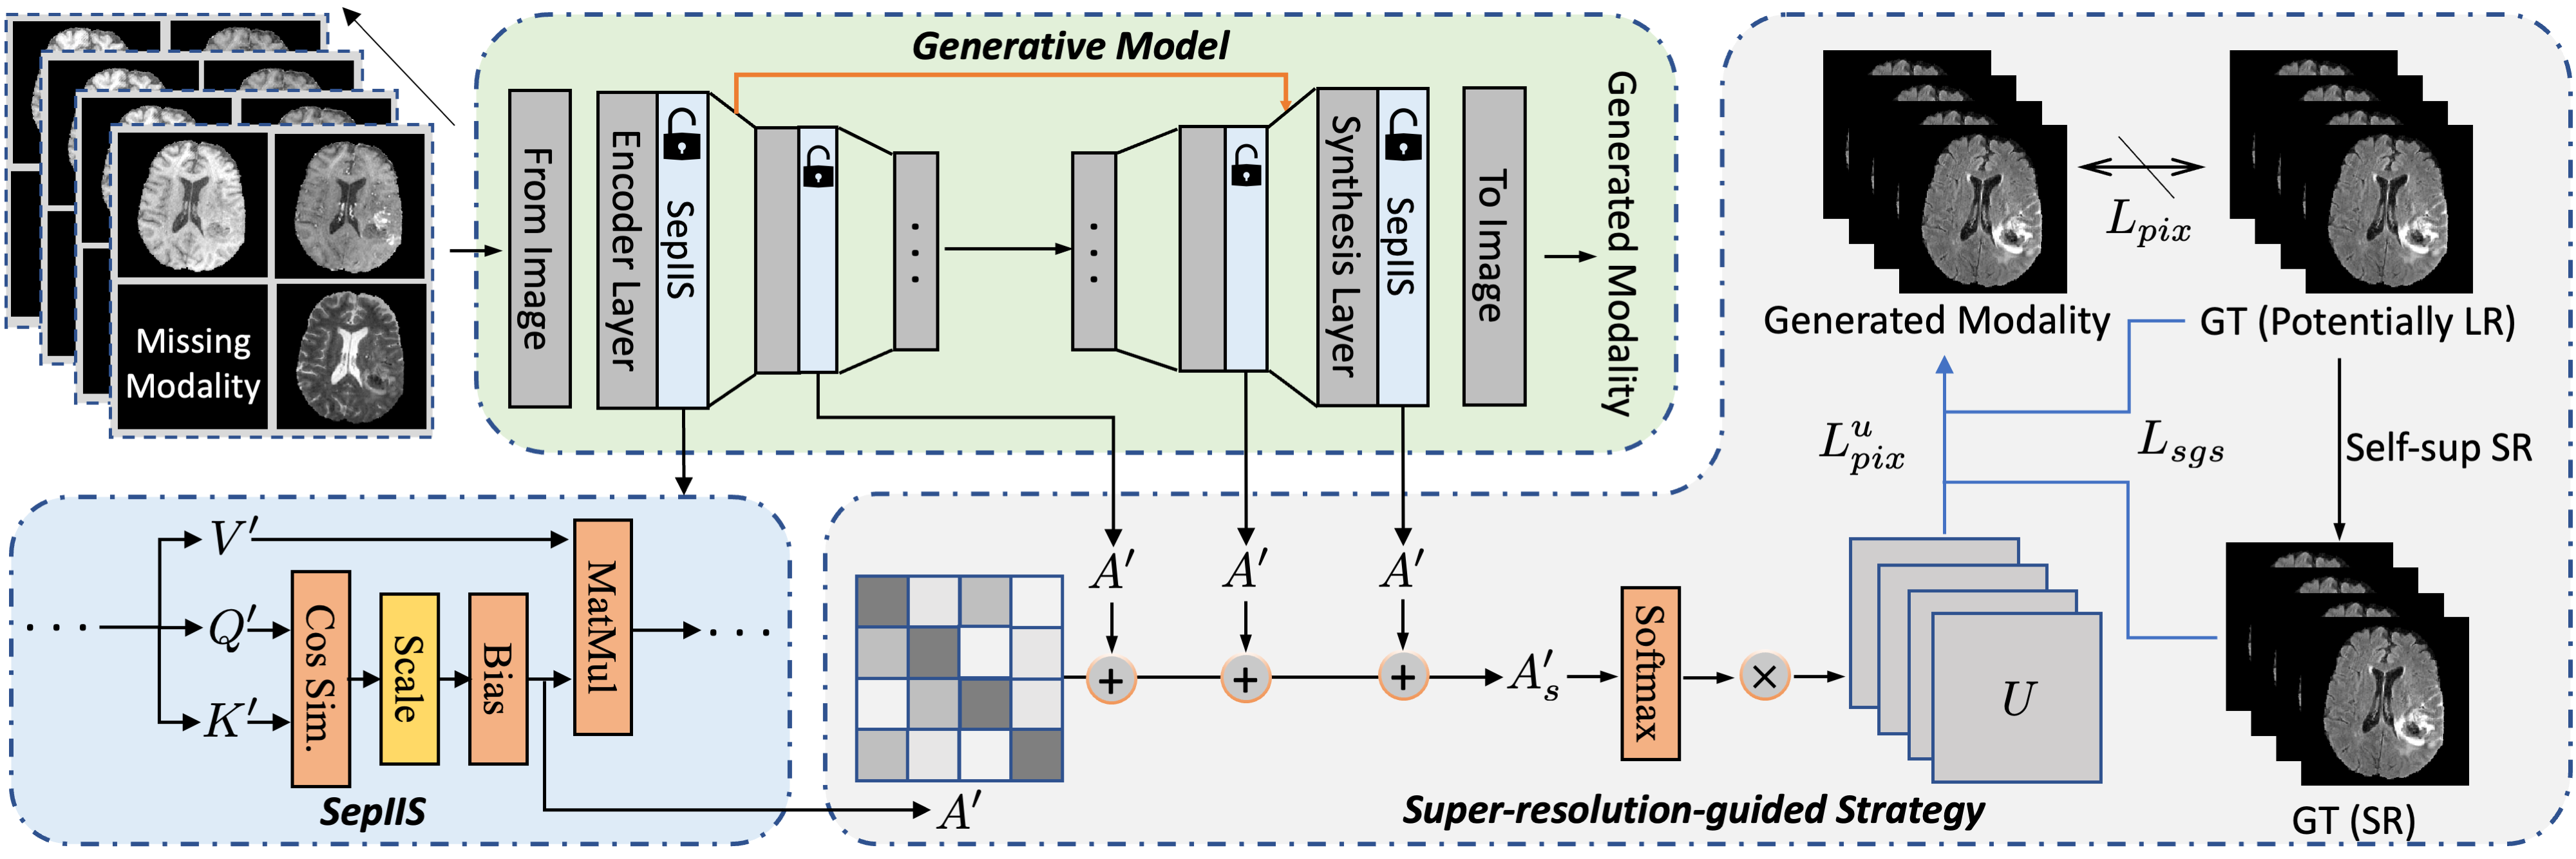
Reconstructing missing modalities of magnetic resonance images (MRIs) is a significant challenge in the medical imaging field. Current generative approaches such as generative adversarial networks (GANs) and diffusion models (DMs) have shown promise in synthesizing high-fidelity 2-D slices. However, they fall short in producing high-quality 3-D results due to their inability to leverage the contextual information across adjacent slices, resulting in low-quality images with poor interplane consistency. This problem is exacerbated when trained on datasets obtained with 2-D scanning protocols, where different MRI modalities have varying resolution between slices, leading to blurry and low-resolution results. To overcome these issues, we propose a novel fine-tuning strategy that can enhance the 2-D multimodal synthesis models to improve both consistency and interplane resolution in 3-D images. We begin by developing a novel attention-based module that can effectively empower generative models to produce 3-D results with high consistency between adjacent slices. Furthermore, we incorporate self-supervised super-resolution (SR) to deal with the varying resolution problem and eventually improve the interplane resolution of generated images. Instead of directly applying SR models that may bring about potential artifacts, we design a novel uncertainty modulation strategy, which optimizes the utilization of super-resolved images for high-quality reconstruction. We extensively evaluate our method through supervised and unsupervised multimodal synthesis using different generative models, including GAN- and DM-based models, all of which demonstrate the superiority and flexibility of the proposed method.
REHRSeg: Unleashing the Power of Self-supervised Super-resolution for Resource-efficient 3D MRI Segmentation
- Accepted to Neurocomputing, 2025;
- Codes are available at https://github.com/zhiyuns/REHRSeg.
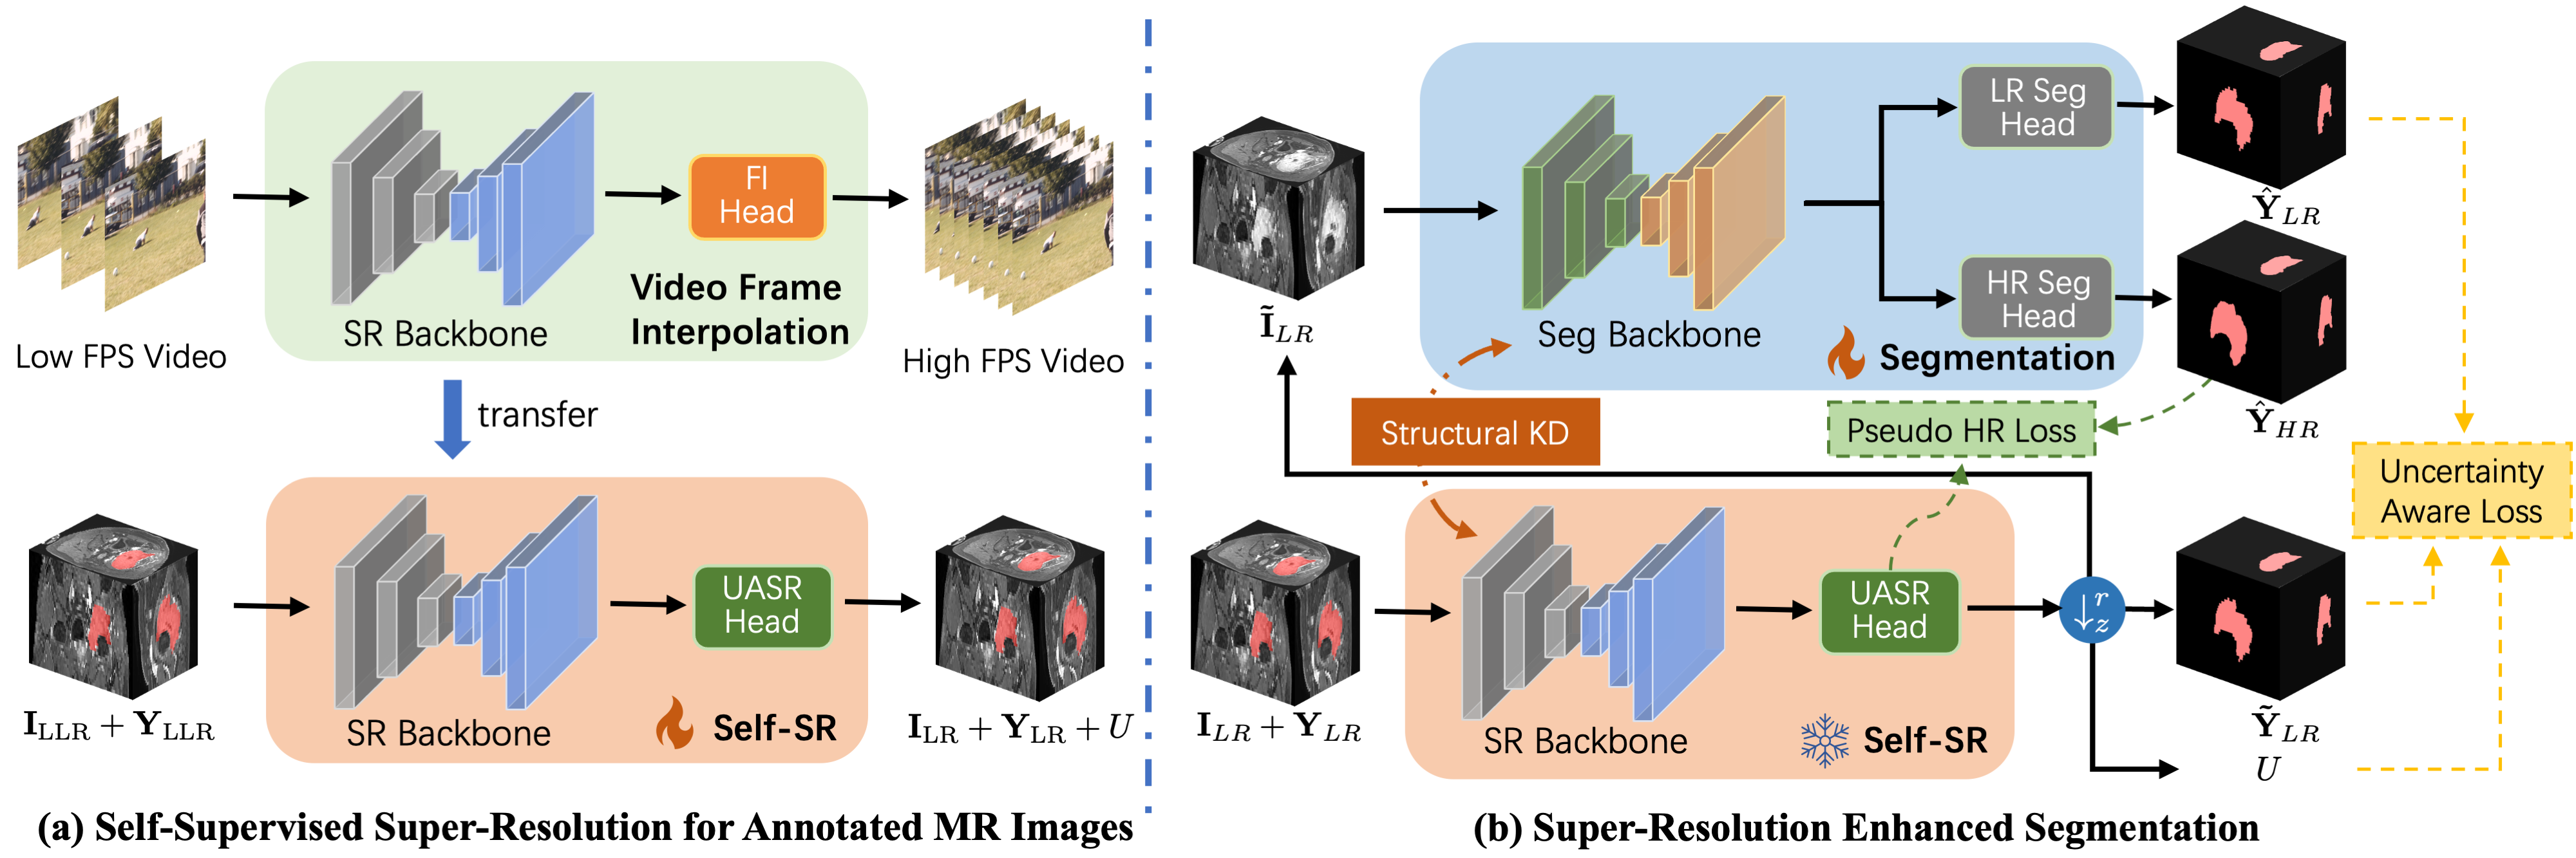
High-resolution (HR) 3D magnetic resonance imaging (MRI) can provide detailed anatomical structural information, enabling precise segmentation of regions of interest for various medical image analysis tasks. Due to the high demands of acquisition device, collection of HR images with their annotations is always impractical in clinical scenarios. Consequently, segmentation results based on low-resolution (LR) images with large slice thickness are often unsatisfactory for subsequent tasks. In this paper, we propose a novel Resource-Efficient High-Resolution Segmentation framework (REHRSeg) to address the above-mentioned challenges in real-world applications, which can achieve HR segmentation while only employing the LR images as input. REHRSeg is designed to leverage self-supervised super-resolution (self-SR) to provide pseudo supervision, therefore the relatively easier-to-acquire LR annotated images generated by 2D scanning protocols can be directly used for model training. The main contribution to ensure the effectiveness in self-SR for enhancing segmentation is three-fold: (1) We mitigate the data scarcity problem in the medical field by using pseudo-data for training the segmentation model. (2) We design an uncertainty-aware super-resolution (UASR) head in self-SR to raise the awareness of segmentation uncertainty as commonly appeared on the ROI boundaries. (3) We align the spatial features for self-SR and segmentation through structural knowledge distillation to enable a better capture of region correlations. Experimental results demonstrate that REHRSeg achieves high-quality HR segmentation without intensive supervision, while also significantly improving the baseline performance for LR segmentation.
Alias-Free Co-modulated Network for Cross-modality Synthesis and Super-resolution of MR Images
- Accepted to MICCAI, 2023;
- Codes are available at https://github.com/zhiyuns/AFCM.
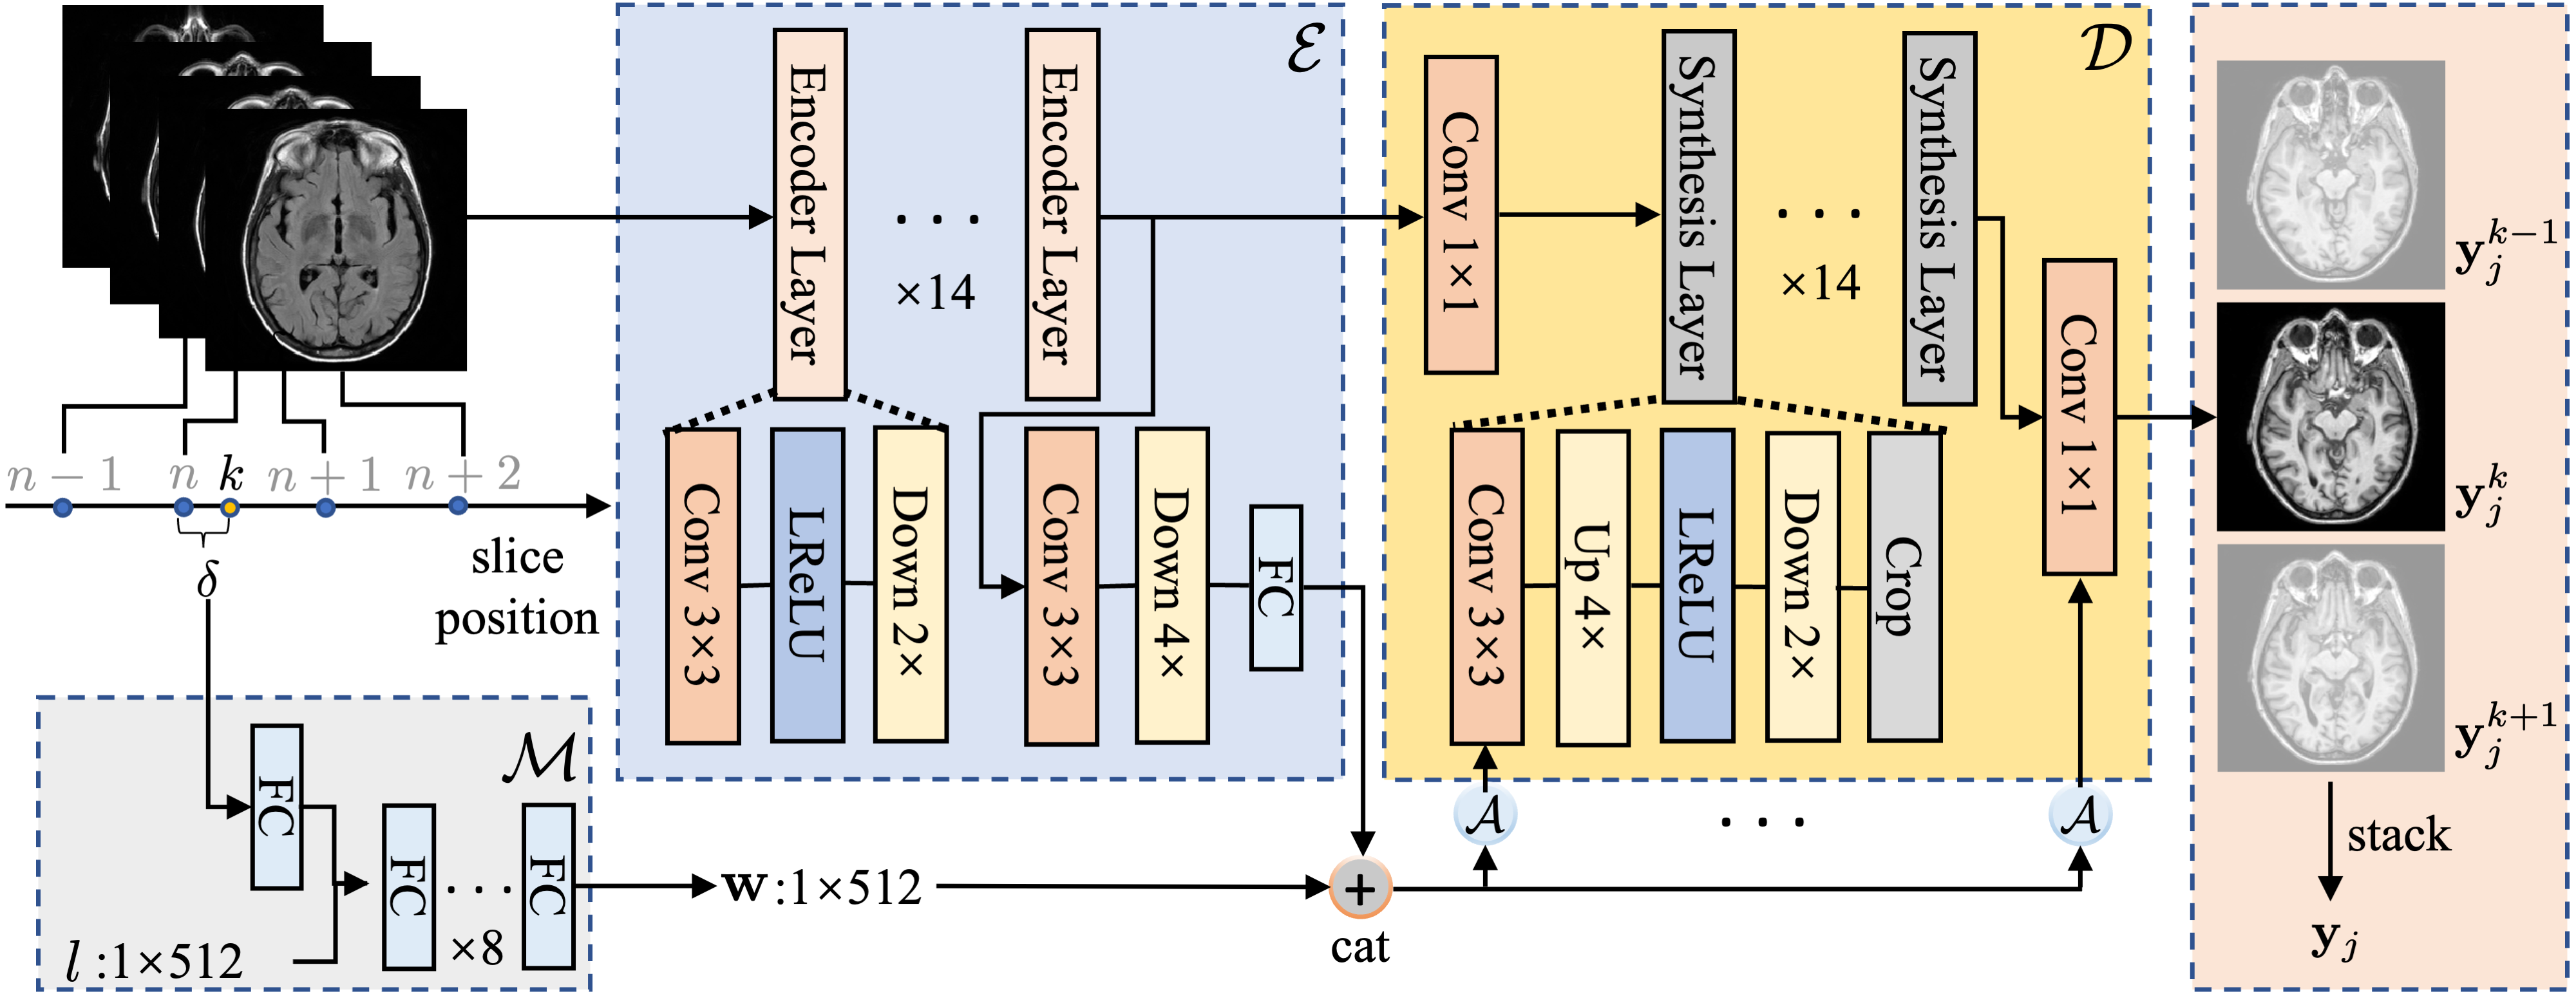
Cross-modality synthesis (CMS) and super-resolution (SR) have both been extensively studied with learning-based methods, which aim to synthesize desired modality images and reduce slice thickness for magnetic resonance imaging (MRI), respectively. It is also desirable to build a network for simultaneous cross-modality and super-resolution (CMSR) so as to further bridge the gap between clinical scenarios and research studies. However, these works are limited to specific fields. None of them can flexibly adapt to various combinations of resolution and modality, and perform CMS, SR, and CMSR with a single network. Moreover, alias frequencies are often treated carelessly in these works, leading to inferior detail-restoration ability. In this paper, we propose Alias-Free Co-Modulated network (AFCM) to accomplish all the tasks with a single network design. To this end, we propose to perform CMS and SR consistently with co-modulation, which also provides the flexibility to reduce slice thickness to various, non-integer values for SR. Furthermore, the network is redesigned to be alias-free under the Shannon-Nyquist signal processing framework, ensuring efficient suppression of alias frequencies. Experiments on three datasets demonstrate that AFCM outperforms the alternatives in CMS, SR, and CMSR of MR images.
Nucleus-aware Self-supervised Pretraining Using Unpaired Image-to-image Translation for Histopathology Images
- Accepted to TMI, 2023;
- Projects are available at https://github.com/zhiyuns/UNITPathSSL.
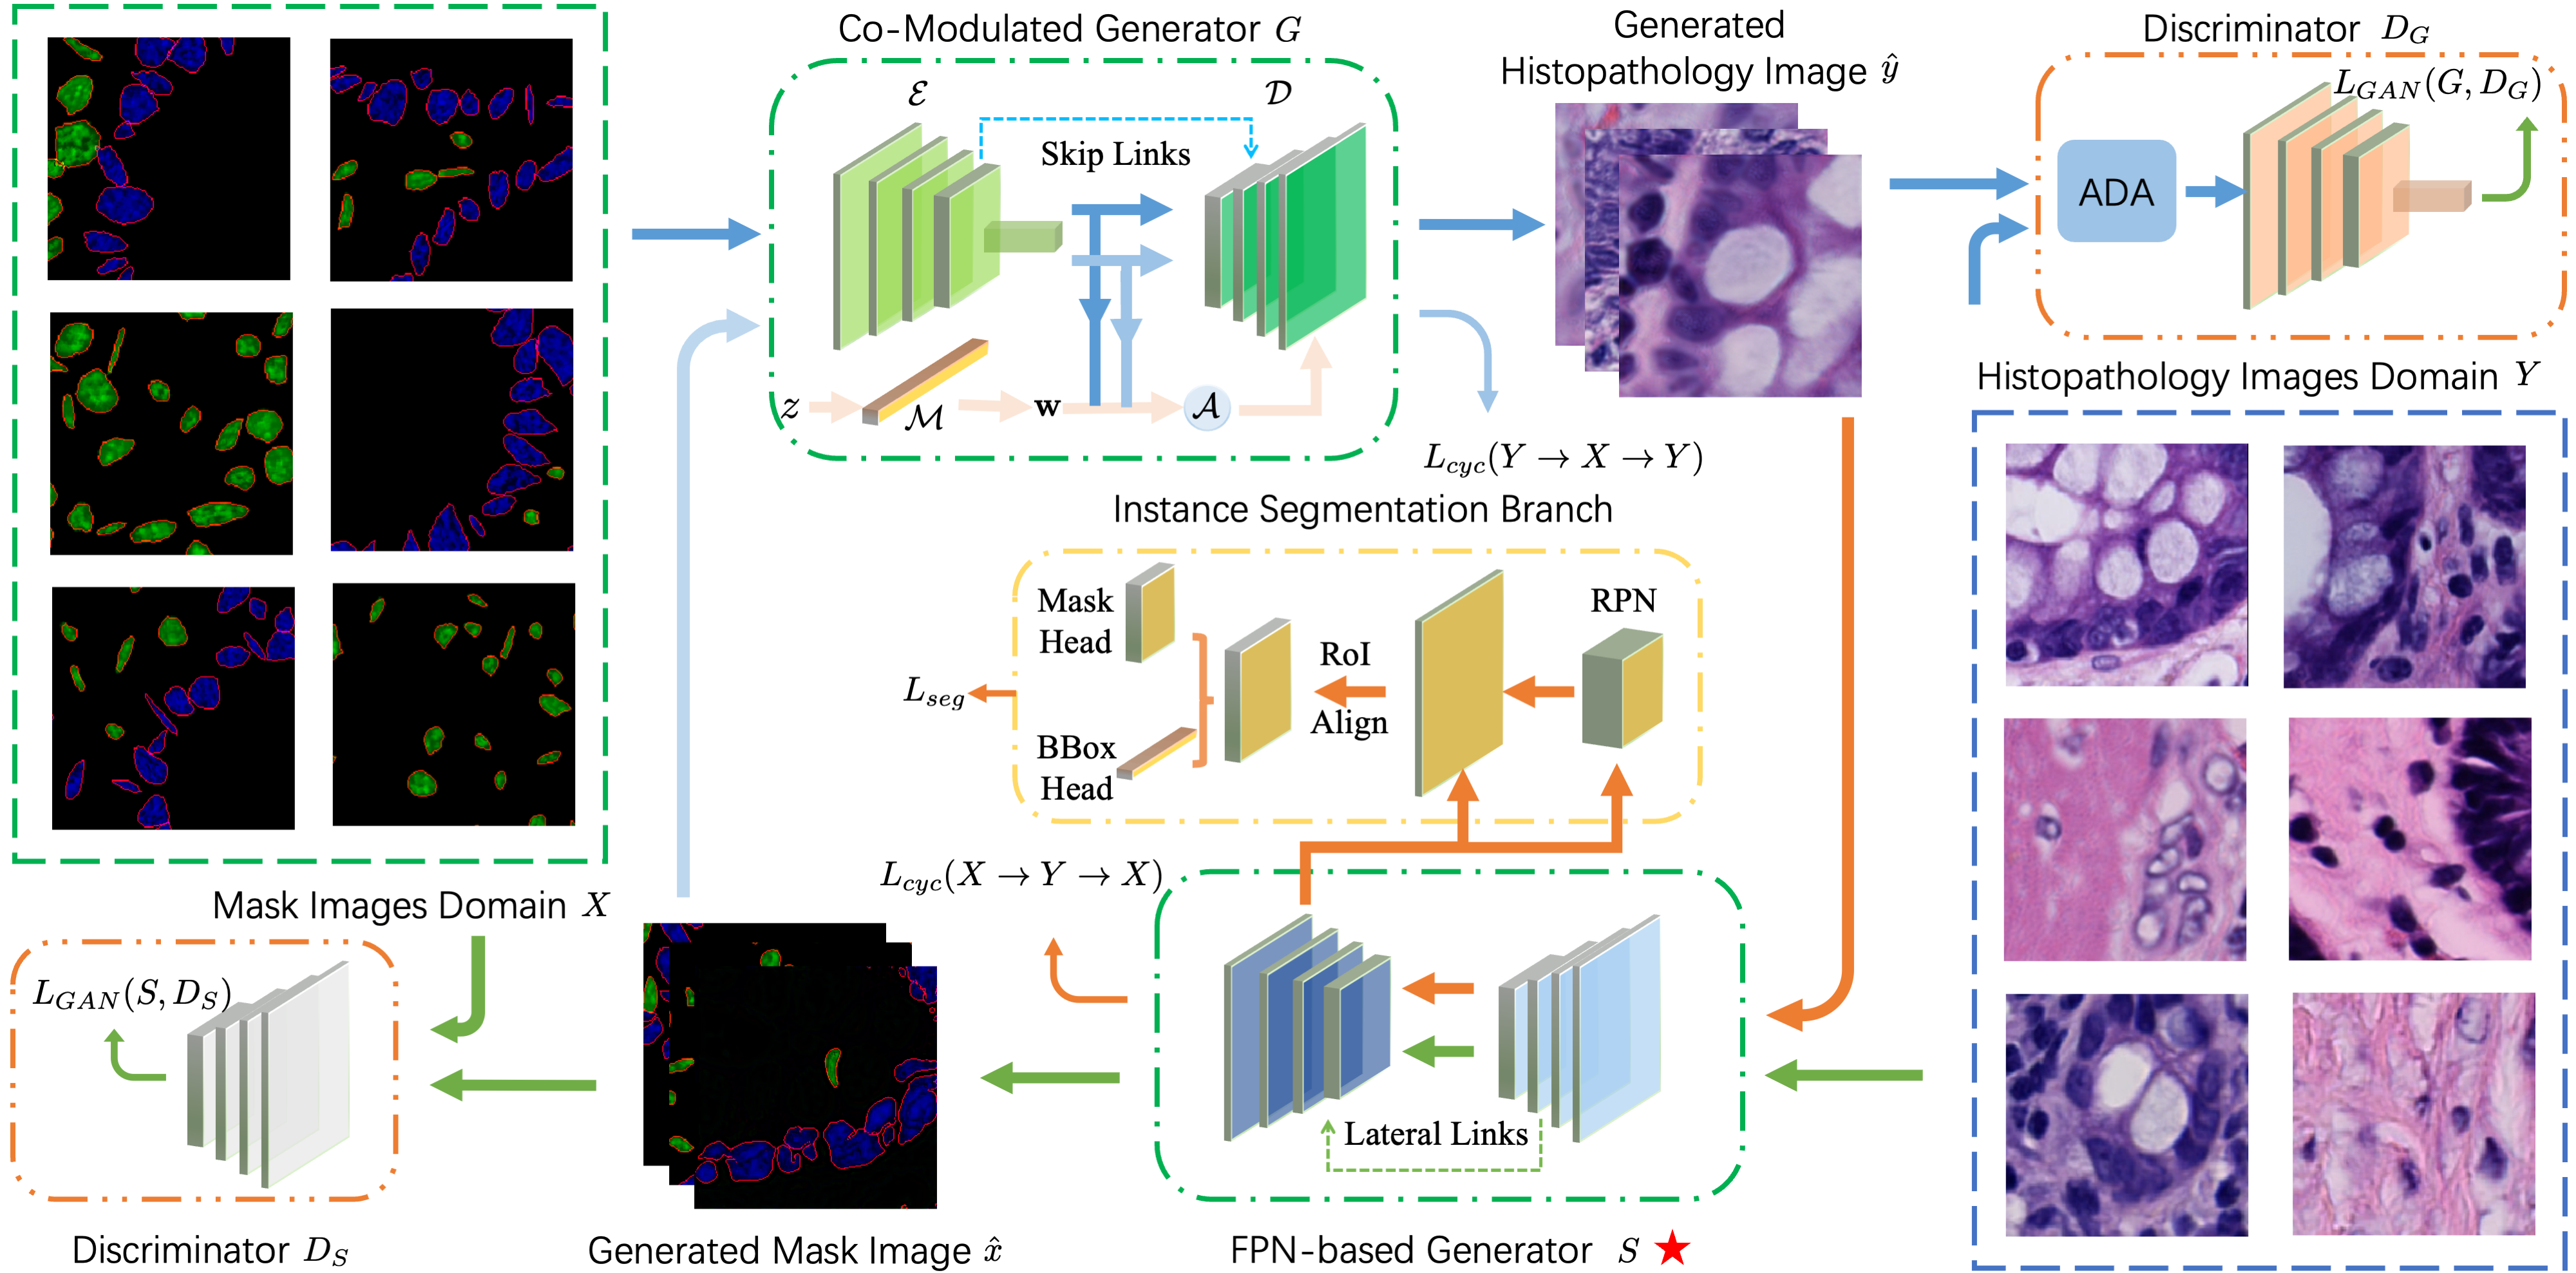
Self-supervised pretraining attempts to enhance model performance by obtaining effective features from unlabeled data, and has demonstrated its effectiveness in the field of histopathology images. Despite its success, few works concentrate on the extraction of nucleus-level information, which is essential for pathologic analysis. In this work, we propose a novel nucleus-aware self-supervised pretraining framework for histopathology images. The framework aims to capture the nuclear morphology and distribution information through unpaired image-to-image translation between histopathology images and pseudo mask images. The generation process is modulated by both conditional and stochastic style representations, ensuring the reality and diversity of the generated histopathology images for pretraining. Further, an instance segmentation guided strategy is employed to capture instance-level information. The experiments on 7 datasets show that the proposed pretraining method outperforms supervised ones on Kather classification, multiple instance learning, and 5 dense-prediction tasks with the transfer learning protocol, and yields superior results than other self-supervised approaches on 8 semi-supervised tasks.